Research
We develop artificial intelligence methods for complex real-world data, particularly in settings where labeled examples are scarce. Our work spans biomedical signals and sleep research as well as natural language, connected by a common interest in reliable representation learning and generalization.
AI for biomedical data and sleep
Sleep dynamics contain information about brain function and disease, but studying these dynamics requires substantial expert effort. We develop AI methods for analyzing the macrostructure and microstructure of sleep, focusing on heterogeneous clinical data and reliable evaluation. We provide our results as tools that researchers can use in practice.
AnySleep: flexible, high-resolution sleep staging
Published in npj Digital Medicine · 2026
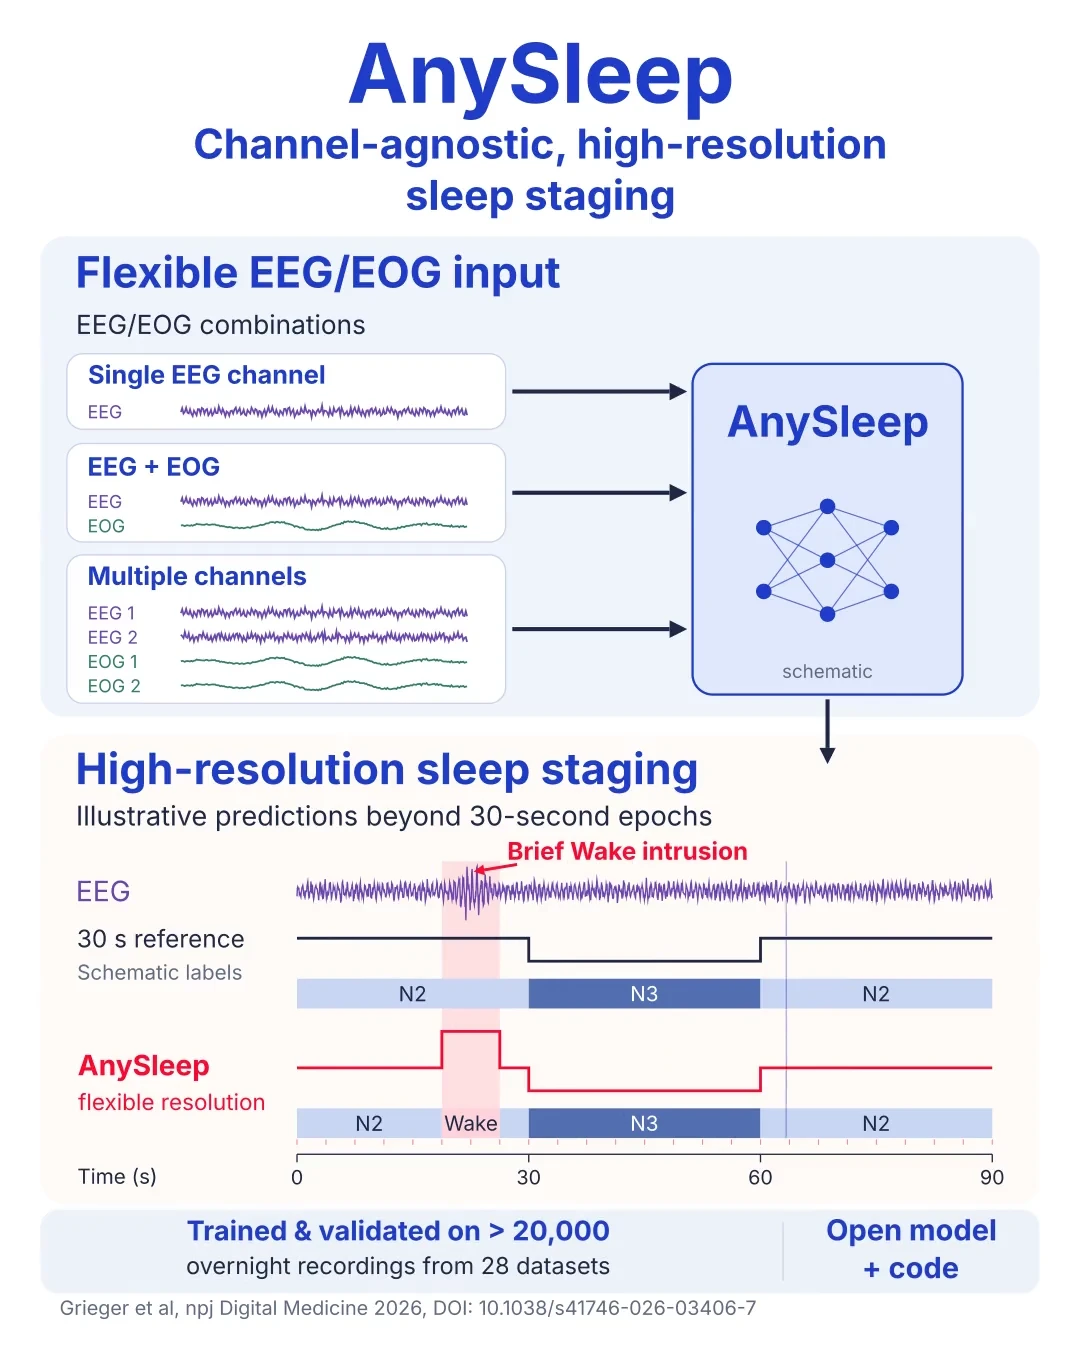
Sleep is traditionally scored in 30-second intervals, which can obscure brief changes in sleep dynamics. With AnySleep, we introduce an open-source deep learning model for flexible, high-resolution sleep staging, evaluated in a study covering more than 20,000 overnight recordings, including independent held-out datasets. AnySleep supports varying combinations of EEG and EOG channels, including single-channel recordings, facilitating large-scale sleep studies across cohorts and clinics with different electrode setups. AnySleep also predicts sleep stages at adjustable temporal resolutions. In retrospective analyses, finer predictions improved discrimination between healthy controls and participants with sleep apnea, narcolepsy type 1, or insomnia. These findings support research into sleep dynamics and potential biomarkers.
Technical focus: channel attention, heterogeneous EEG/EOG montages, multi-center generalization, and high-resolution sleep dynamics.
SUMO: identifying sleep spindles with expert-level performance
Published in Scientific Reports · 2022
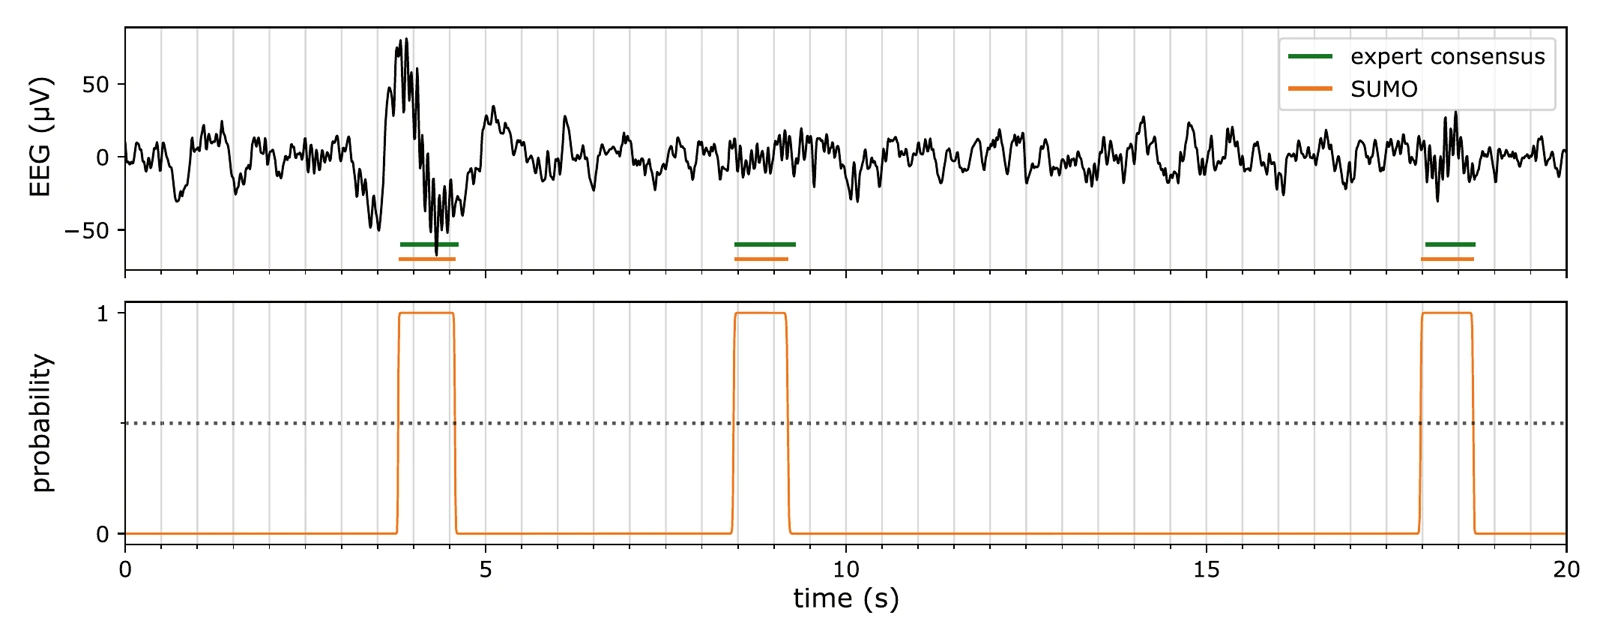
Sleep spindles are brief patterns in EEG recordings associated with memory and neurological or psychiatric conditions. Manual identification is time-consuming, and experts often disagree. We therefore trained SUMO, a deep learning model, using consensus annotations from multiple specialists. The model outperformed the previous state-of-the-art detector and most individual experts, supporting more reproducible and scalable studies of sleep microstructure.
Technical focus: neural event detection, expert-consensus labels, inter-rater variability, and generalization across age groups.
SomnoBot: use our models without uploading patient data
SomnoBot makes AnySleep and SUMO available directly in a web browser. The neural networks run locally on the researcher's computer, so polysomnographic recordings are not uploaded to us or another party. Researchers can perform sleep staging and spindle detection without installing specialist software, making validated analysis tools accessible while keeping sensitive data local.
Our end-to-end study shows how automated sleep staging and spindle detection can reproduce important findings from an expert-led study in minutes rather than months. Read the study.
Pretraining without patient data
Published in Algorithms · 2025
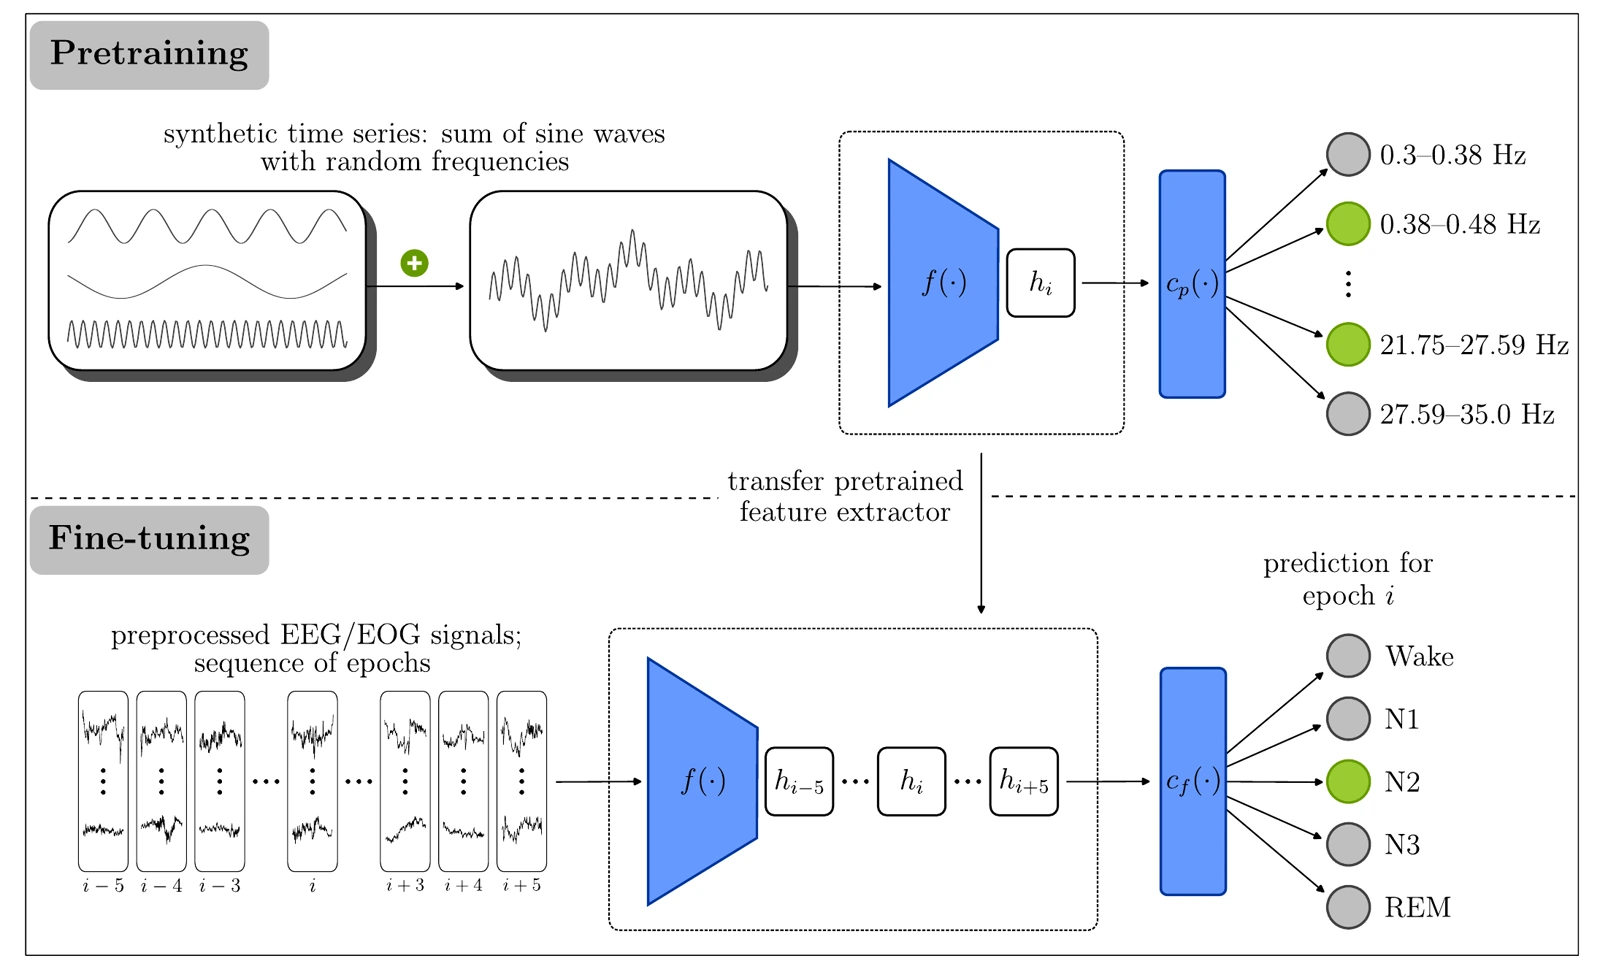
Medical AI development is often constrained by small datasets and costly expert annotations. We studied whether a neural network could first learn frequency-related structure from randomly generated synthetic time series and then transfer that knowledge to sleep staging. Frequency pretraining improved performance over training from scratch when only a small number of subjects or limited labeled data were available.
Technical focus: synthetic time series, frequency prediction, representation pretraining, transfer learning, and label efficiency.
Language modeling for low-resource settings
Many advances in language modeling depend on extensive English-language or task-specific data. We investigate how pretrained language models can be adapted efficiently to specialized German-language tasks, including the analysis of online discourse and political text. Our work combines competitive shared-task evaluation with methods that make better use of limited annotations.
Detecting positive language in YouTube comments through span-level training
Published in KONVENS Workshop Proceedings · 2025
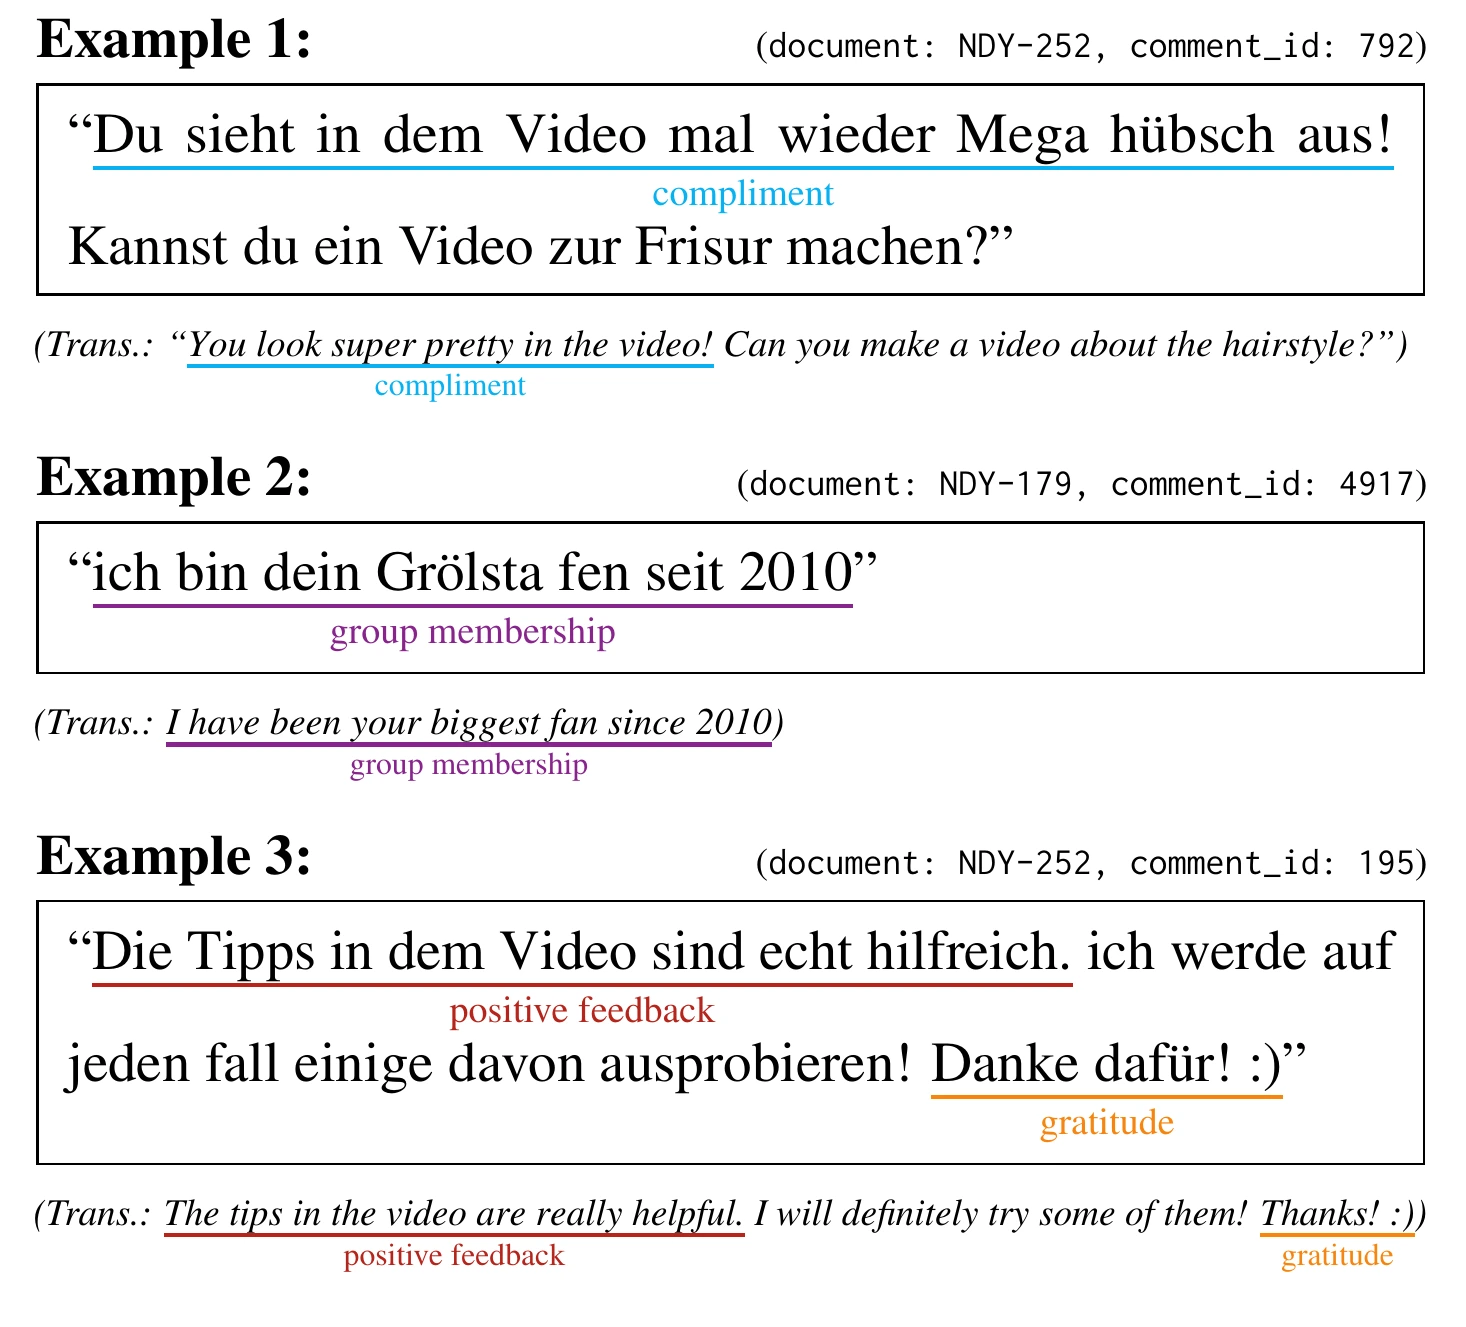
Positive and supportive online communication can foster more constructive public discussion, but identifying such language at scale is difficult. For GermEval 2025, we trained language models to detect "candy speech" in 46,000 German YouTube comments. Our approach ranked first in both subtasks of the international GermEval 2025 competition. Training models to identify specific supportive phrases improved binary comment classification compared with training on comment-level labels alone.
Technical focus: multilingual language models, span-level BIO tagging, specialized fine-tuning, and German social-media text.
Classifying German Facebook comments: toxicity, engagement, and factual claims
We combined fine-tuned German BERT and ELECTRA models to identify toxic, engaging, and fact-claiming comments. The resulting ensembles achieved first place in the international GermEval 2021 competition and established an early foundation for our work on specialized German-language modeling.
Efficiently adapting large language models with QLoRA
We explored QLoRA soon after its introduction to adapt Llama 2 for speaker attribution in German parliamentary debates, identifying who said what to whom. The approach achieved competitive performance in the international GermEval 2023 competition without relying on traditional linguistic features and demonstrated the potential of parameter-efficient adaptation for specialized non-English tasks.
Technical focus: Llama 2, QLoRA, prompt-based cue and role prediction, and semantic role labeling.
Selected publications
- Grieger, N., Raskob, J., Mehrkanoon, S., and Bialonski, S. 2026. AnySleep: a channel-agnostic deep learning system for high-resolution sleep staging in multi-center cohorts. npj Digital Medicine 9, 829. Read the publication.
- Kaulen, L. et al. 2022. Advanced sleep spindle identification with neural networks. Scientific Reports 12, 7686. Read the publication.
- Thelen, C. R., Blaneck, P. G., Bornheim, T., Grieger, N., and Bialonski, S. 2025. AIxcellent Vibes at GermEval 2025 Shared Task on Candy Speech Detection: Improving Model Performance by Span-Level Training. In Proceedings of the 21st Conference on Natural Language Processing (KONVENS 2025): Workshops, pages 398-403. Read the proceedings paper.